Contact Info
106 Anne Rd, Knoxfield VIC 3180, Australia
+61 (03) 82023009
info@ninjaweb.com.au
Contact usRecommended Services


Supported Scripts
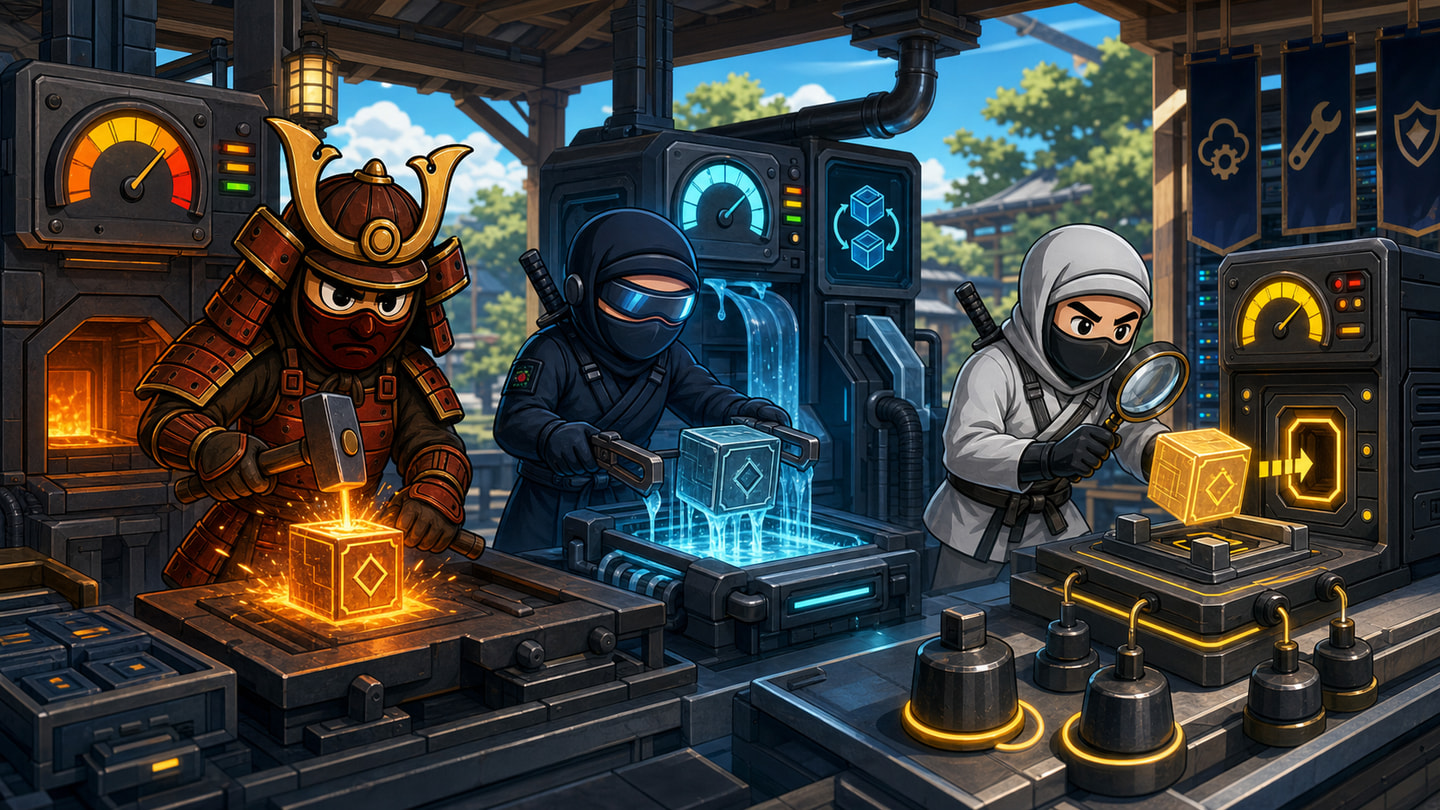

The Digital Forge is not a claim that technology becomes reliable through intensity or clever branding. It is a practical way to describe the work that happens after software, hosting and automation have been installed. Raw components become dependable systems only when pressure, ownership, recovery and inspection shape them.
A tool can be installed in an afternoon. Reliability must be earned across real traffic, staff changes, supplier failures and the moment somebody needs to restore what was working yesterday.
Installation Is Raw Material, Not Finished Reliability
A website, CRM, server or automation can pass a launch checklist and still be operationally weak. The accounts may exist, integrations may connect and the homepage may load, but nobody knows who owns an alert, which backup can be restored or what should happen when one supplier changes its API.
The Digital Forge starts by refusing to call installation delivery. Installation provides the material. The operating model turns that material into something the business can trust.
Heat Reveals the Weak Parts
In a forge, heat changes what can be seen and shaped. In a digital system, controlled pressure reveals assumptions hidden by quiet conditions. Load tests, busy campaign windows, large imports and simultaneous staff activity show where capacity, queries and handoffs begin to fail.
This does not mean attacking production until it breaks. Use staging, controlled test windows and realistic scenarios. Record the expected limit, the observed result and the person who decides whether the system is ready.
The result should create a decision, not just a chart. Increase capacity, reduce unnecessary work, change the design or document the operating limit so the business knows what the system can safely carry.
A system that has only been tested when nothing difficult is happening has not been tested for the moment the business will need it most.
Shaping Means Giving Every Component an Owner
Reliability has a human shape. DNS, hosting, WordPress, forms, email, CRM, payments, backups and monitoring each need a named owner. Without that map, every incident begins with supplier archaeology.
- Who receives the first alert?
- Who can approve a production change?
- Who contacts the external supplier?
- Who explains the business impact?
- Who confirms that recovery is complete?
One person does not need to perform every task. The system needs clear authority and a handoff that works when the primary owner is unavailable.
Quenching Is the Recovery Test
A backup report is not proof of recovery. The proof is a controlled restore that confirms the files, database, credentials and surrounding configuration can return together. The team should know the recovery point, expected recovery time and verification path.
Rollback deserves the same treatment. A deployment may have a previous version, but data changes, plugin migrations and external integrations can make reversal more complicated than replacing files. Write and test the return path before the forward change.
Inspection Requires Monitoring That Leads to Action
Monitoring is useful only when a signal reaches someone who can interpret it. Uptime, response time, queue depth, failed jobs, storage, security events and backup health may all matter, but a wall of alerts creates another kind of blindness.
Each important signal needs a threshold, owner, response and escalation rule. Review alerts that never lead to action. Either the signal is not useful, the threshold is wrong or the operating team has stopped trusting it.
Test the notification path as well as the metric. An accurate alert that reaches an abandoned mailbox is not monitoring; it is evidence being delivered to nobody.
Tempering Is the Work After the First Success
A system is not finished because it survived one launch. Staff, traffic, software and suppliers change. Reliability improves when the team reviews incidents, removes obsolete access, tests restores, updates runbooks and closes actions instead of collecting them.
Tempering is repetition with evidence. The system returns to pressure after each improvement and proves that it is stronger in the exact area that previously failed.
This is also where cost becomes visible. Repeated emergency work is expensive; a measured improvement cycle turns that same effort into fewer surprises and clearer operating decisions.
A Reliable System Has a Memory
Good operations preserve decisions. Record why a configuration exists, which change introduced it, who approved it and how to reverse it. Keep incident timelines, restore results and supplier contacts where the next operator can find them.
That memory prevents the business from paying twice for the same discovery. It also makes staff transitions less dangerous because operational knowledge belongs to the system, not only to one person’s inbox.
The Forge Produces Confidence, Not Theatre
NinjaWeb uses the forge idea to describe disciplined delivery, not a visual costume. Business systems, managed web hosting and managed WordPress hosting become valuable when ownership, monitoring and recovery connect them to the business.
Choose one system the business cannot afford to lose. Test its owner, load, alert, rollback and restore path. Fix the weakest result and test again. Reliable systems are not installed once. They are tempered until confidence is supported by evidence.